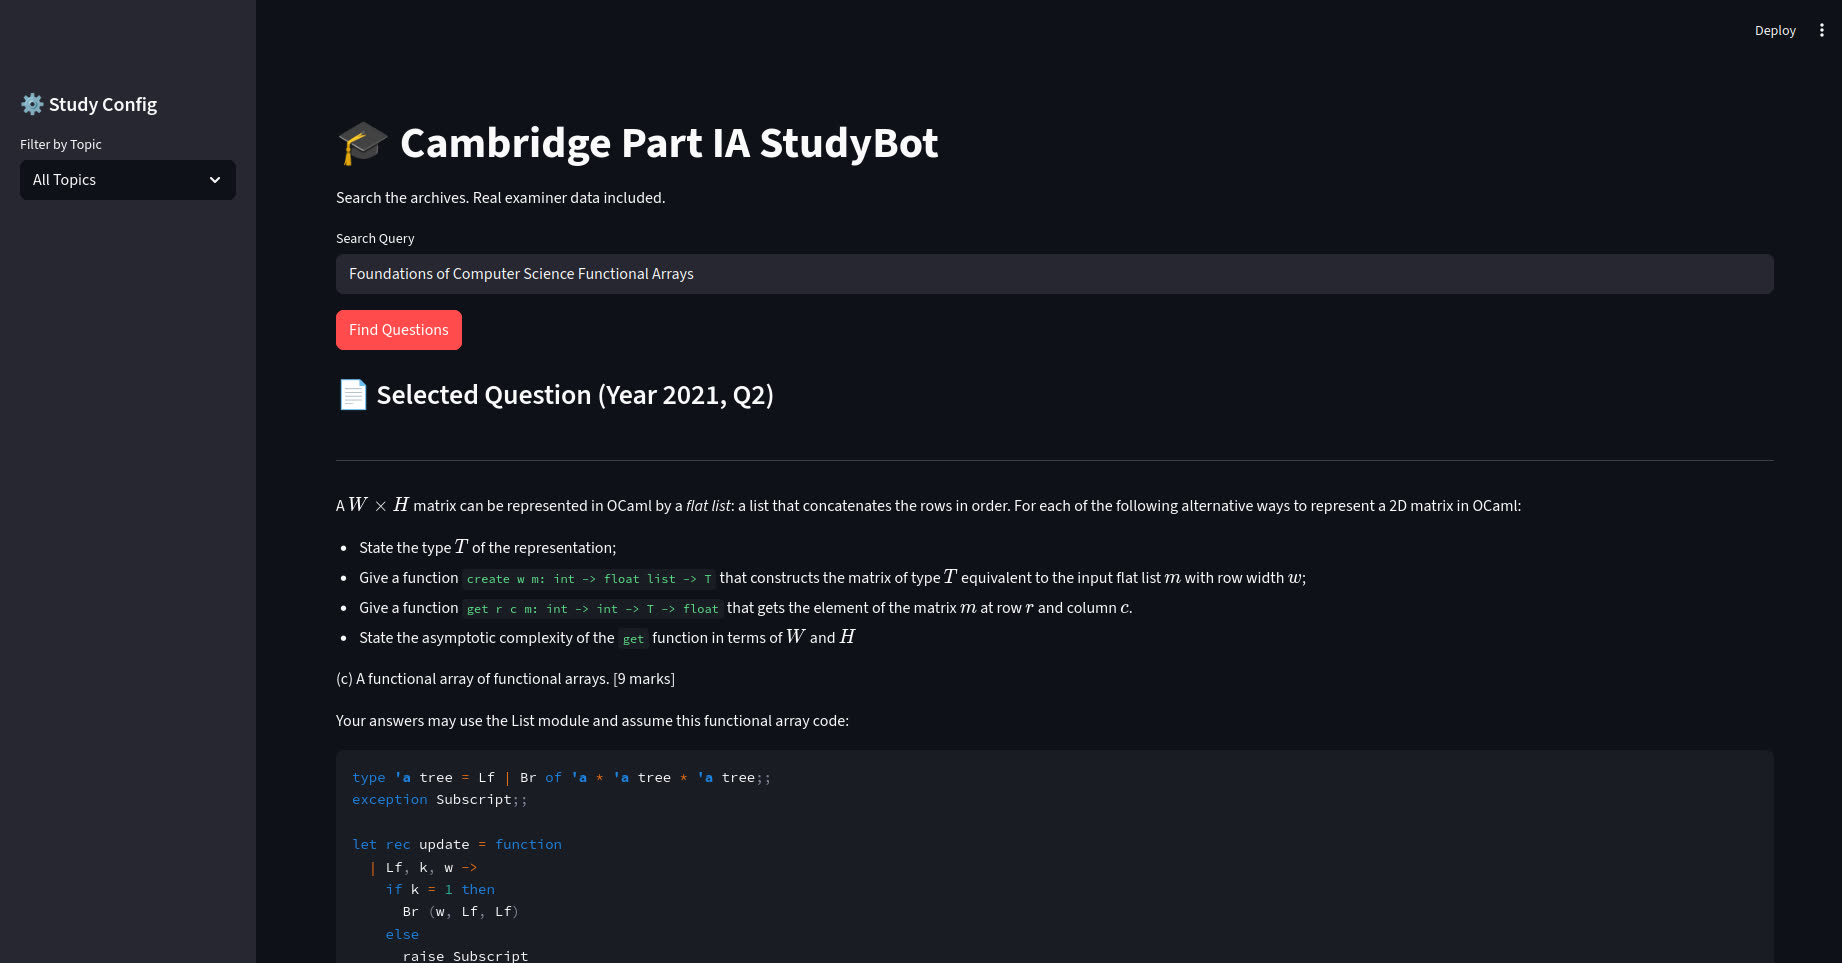
Overview
Past papers are the best revision there is, and the hardest to search. They're PDFs full of maths, and the same idea goes by different names from year to year.
Keyword search fails on both counts. Most of the work turned out to be getting clean data in: if the LaTeX comes out mangled, no amount of clever retrieval fixes it.
How it works
Scrape the public papers
A downloader pulls the question-paper PDFs from the Computer Lab's site.
Read them with vision, in parallel
Pages are rendered with PyMuPDF and read by Gemini Vision, which keeps formulae and code intact. Running it multithreaded cut processing time by 75%.
Add what the examiners said
A second pipeline reads the Examiners' Reports and attaches difficulty and common mistakes to each question.
Search by meaning
Questions are embedded into a local ChromaDB store; a Streamlit UI searches by concept, filters by topic and hides AI hints until you ask.